T-06 Province II · The Ateliers The Workshop Quarter 5 min 6 of 21
Generative Foundations: Latent Variables, Diffusion & Flow
The four major families of model that learn to generate: VAEs, GANs, autoregressive models, and diffusion/flow methods.
In one sentence There are a handful of very different recipes for turning nothing into something realistic, each with its own trade-offs.

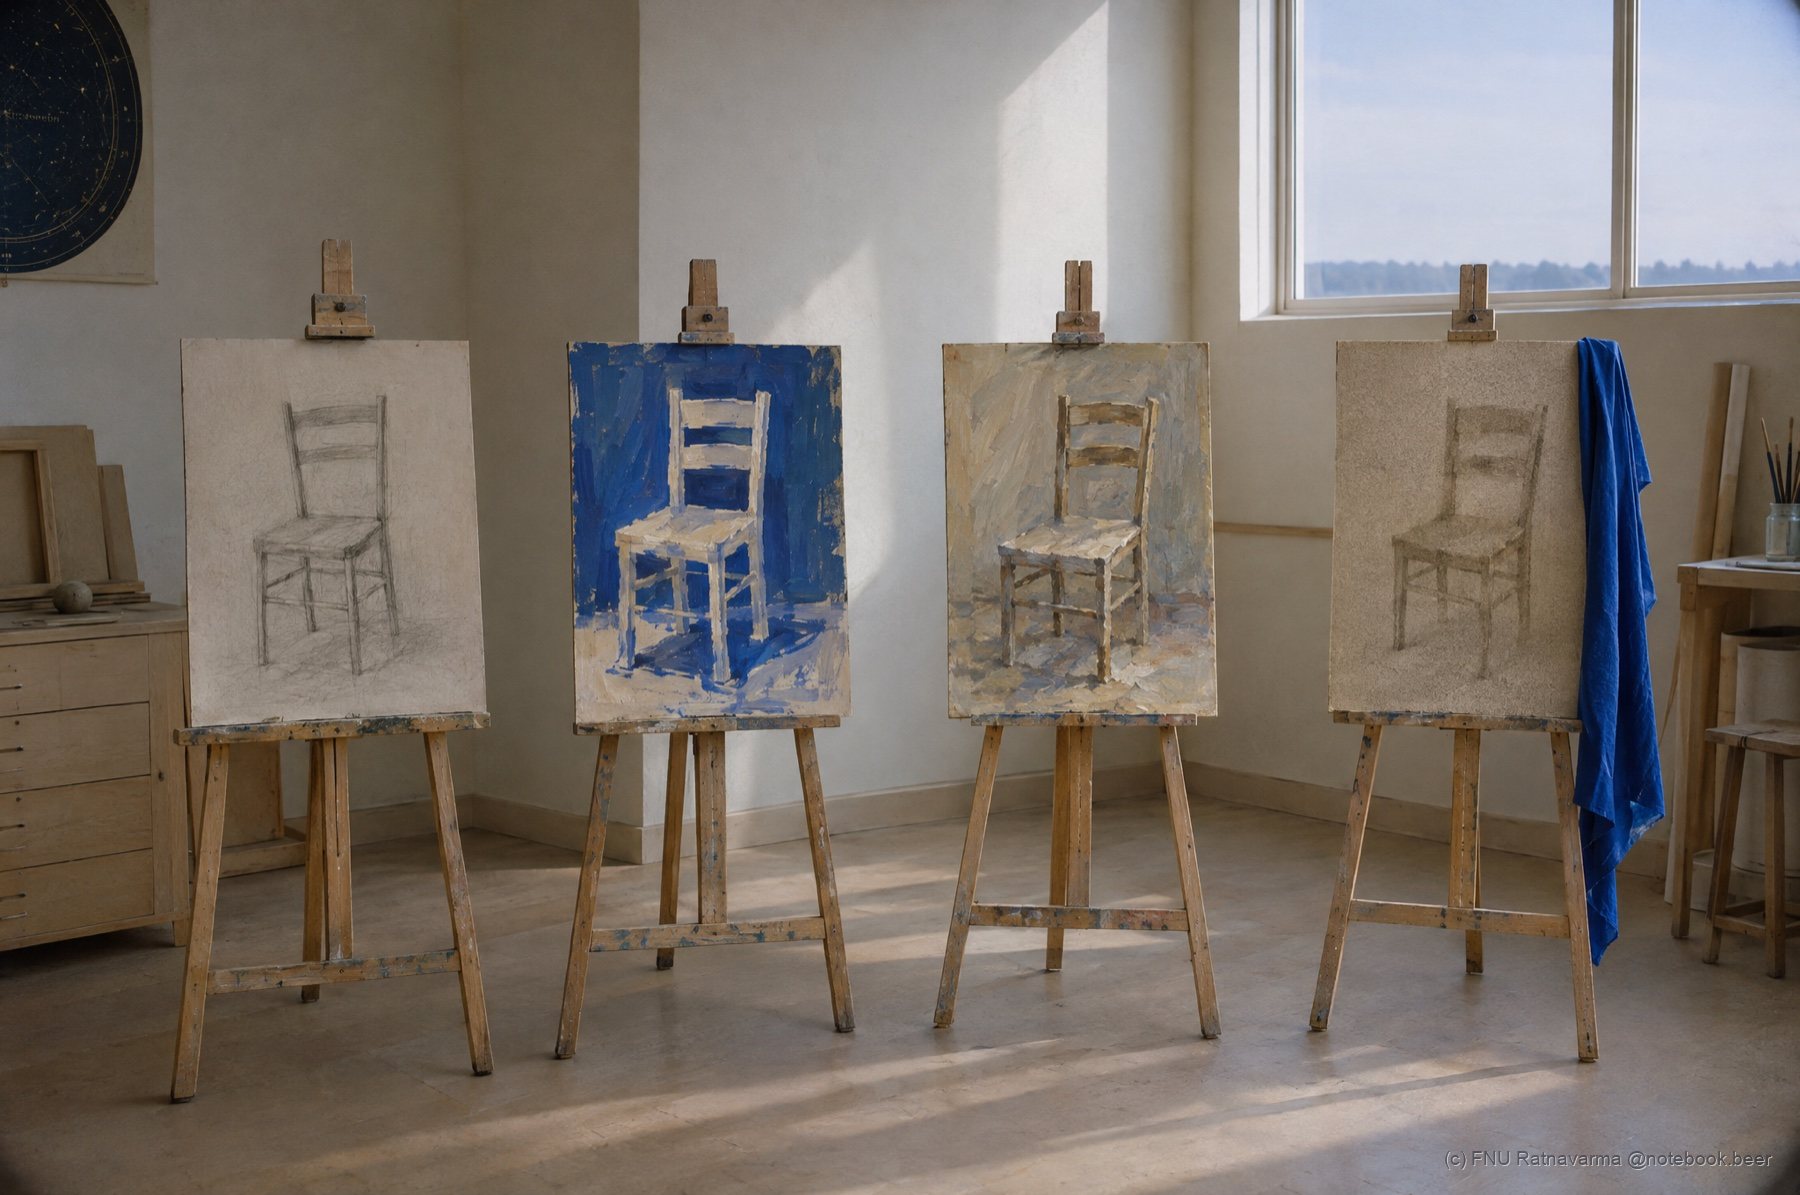
Ask four artists to paint the same chair. Each one has a different way of working.
The first artist sketches a rough shape in a few lines. Then she fills in the details from that sketch. The rough sketch is like a secret code for the chair.
The second artist paints fast and bold. A grumpy critic stands beside him. The critic says "fake" or "real" for every painting. The artist keeps trying until the critic is fooled.
The third artist paints one stroke at a time, always left to right. Each new stroke depends on the strokes before it. She never goes back.
The fourth artist starts with a page full of messy scribbles. Then she cleans them up a tiny bit at a time. Slowly a chair appears out of the mess.
All four end with a chair. But each way is good at something different.
The sketch artist is quick and tidy. The critic's artist makes sharp, bold pictures. He and the critic argue a lot, though.
The stroke-by-stroke artist is careful about order. The scribble cleaner makes the most beautiful pictures. She is also the slowest.
Computers that make new pictures, sounds or stories use these same four ways. Scientists call them generative models. Each one turns nothing into something that looks real.
World models borrow these ways to imagine what happens next. A machine that imagines tomorrow's weather picks the way that fits the job.
Try this at home with your family. Each person draws a cat using one of the four ways.
One sketches first. One draws while someone else says "fake" or "real." One draws only left to right. One starts from scribbles and erases.
Then line up the four cats. Which way was fastest? Which cat looks best?

Four families learn to generate. They differ on four properties. Two are sample quality and training stability. The other two are likelihood guarantees and inference speed.
No family wins on all four.
Variational autoencoders learn a latent variable and a decoder. Kingma and Welling (2013) made them trainable with the reparameterization trick. Training maximizes a lower bound on likelihood, the ELBO. Ha and Schmidhuber's 2018 world model used a VAE as its vision module.
The known VAE failure is posterior collapse. A strong decoder learns to ignore the latent entirely. The KL term falls toward zero.
Bowman et al. (2016) met this with text VAEs. They answered it with KL annealing and word dropout on the decoder.
GANs (Goodfellow et al., 2014) replace explicit likelihood with a game. A generator tries to fool a discriminator.
Samples are often sharp. Training is often unstable. There is no likelihood to check.
Autoregressive models factor a joint distribution into a chain of conditionals. They generate token by token and train with teacher forcing. They compose naturally with sequential decisions. They also inherit compounding error over long rollouts.
Diffusion and flow models learn to reverse a gradual noising process. Flow matching instead follows a continuous path from noise to data.
Training is stable and sample quality is strong. Ho et al. (2020) reported an FID of 3.17 on CIFAR-10 with DDPM.
The cost sits at sampling time. DDPM ran 1,000 denoising steps per sample. That is why diffusion leads in visual fidelity and lags in real-time use. T-07 covers this family in depth.
Within a world model, the backbone sets the character of its imagination. Autoregressive backbones fit step-by-step decision making. Diffusion and flow backbones lead wherever visual fidelity is the priority.
Here is the meter version, from a toolkit lab of mine. I generated 4,000 daily load curves of 96 points each.
Three hidden knobs made them. The knobs were base load, the hour of the peak and its height. An autoencoder squeezed each curve into 3 numbers and redrew it.
Reconstruction error was 0.00096 on curves that run from about 0.3 to 3.0. One latent tracked base load with a correlation of 0.82. Another tracked peak time at 0.84. Peak height came through weakly, at 0.46 at best.
Nobody told the network what the knobs were. Compression keeps what the loss pays for. A VAE on the same curves would add sampling. A planner could then draw plausible load days for a study.
What to measure depends on the family. For VAEs, track KL per latent dimension to catch collapse. For GANs, check diversity, since mode collapse hides behind sharp samples. For any backbone, test samples on the decision they feed, beside image or curve scores.
I would recommend to name the property the application needs before choosing. Pick the backbone from that list.

None of the four generative families is strictly best. Each is a different point on a trade-off. Two of the properties in play are sample quality and training stability. The other two are likelihood guarantees and inference speed.
A team choosing a world model backbone should name the property the job needs. Defaulting to whichever architecture is most publicized this year is the common mistake.
The money shows up in two places. Training cost is the first. GANs can take many restarts before they train well. Diffusion and flow models train more predictably.
Inference cost is the second. It repeats every day.
Diffusion's lead in visual quality comes with a real speed cost. Classic diffusion sampling ran many steps per output. For any real-time or interactive use, that cost multiplies by every call.
Likelihood matters for risk work. A VAE or an autoregressive model can say how probable an outcome is. A GAN cannot. If a regulator or an auditor asks how likely a scenario was, that difference matters.
For a utility the uses split cleanly. Offline planning studies can afford slow, high-quality samples. A dispatch or control loop needs speed and a stable answer.
Synthetic load days for testing need diversity. They also need proof they are realistic.
I would recommend to write the needed property into the requirements before any vendor demo. That keeps the decision tied to the job rather than the headline.
The risk of skipping that step is quiet. A beautiful generator gets bought for a task that needed honest probabilities or low latency. The gap shows up months later in cost or in trust.
The question I would ask is this. Which property does this use case need most? What did we give up to get it?
Quick check
Key terms
Further reading
- Auto-Encoding Variational Bayes Diederik P. Kingma, Max Welling, 2013 The VAE and the reparameterization trick that made latent-variable models trainable.
- Generative Adversarial Networks Ian J. Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, Yoshua Bengio, 2014 The adversarial game between a generator and a discriminator.
- Generating Sentences from a Continuous Space Samuel R. Bowman, Luke Vilnis, Oriol Vinyals, Andrew M. Dai, Rafal Jozefowicz, Samy Bengio, 2016 Where posterior collapse shows up plainly, with KL annealing and word dropout as fixes.
- Denoising Diffusion Probabilistic Models Jonathan Ho, Ajay Jain, Pieter Abbeel, 2020 The paper that made diffusion practical. FID 3.17 on CIFAR-10.
- From Autoencoder to Beta-VAE Lilian Weng, 2018 The latent-variable family explained step by step.